

Mandalorian
Explorer III
March 12, 2026
Solved

EMS server 7.4.5 - Internal Server Error

  • March 12, 2026
  • 6 replies
  • 574 views

Hi,
We recently released two Linux VMs (Ubuntu 24.04 LTS) to configure the EMS server and external DB Postgres. The architecture is EMS with standalone remote DB without Docker (as reported on the Fortinet official document).

With this introduction, I'll explain that the problem we encountered occurred 10 days after completing the configuration.

Suddenly, the EMS GUI was no longer usable, displaying an error 500 (see image below). Both VMs, the one hosting the EMS and the one hosting the external DB, were correctly reachable via SSH.
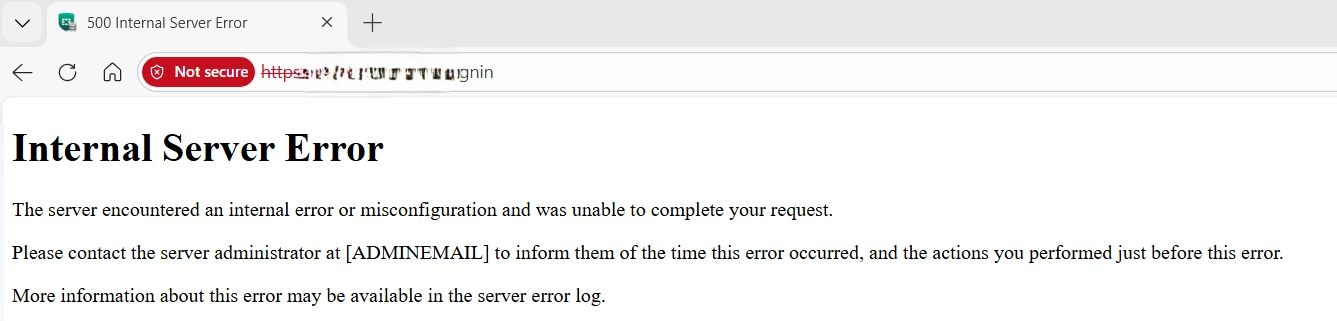
abc.png


As additional information, I'd like to point out that the EMS server and external DB are on the same network and there are no network devices in between them. Furthermore, the hardware resources of both VMs are oversized compared to Fortinet's minimum requirements, and during the error, we didn't detect any problems or resource spikes on the VMs (e.g., disk full or resource spikes).

Since the error persisted, we first attempted to restart the systems in this order: first the external DB, then the EMS server, but the situation remained the same.

Subsequently, following a Fortinet KB, we extracted the logs and attempted to restart the Apache process with this command:

"emscli service restart --name apache2", but even after this attempt, the 500 internal server error persisted.


While analyzing the extracted logs, we detected a message:


FATAL: server login has been failing, try again later (server_login_retry)

(SQLSTATE 08P01)


While we were investigating, some system administrators told us that the 500 error was due to an incorrect timezone and that a control script called tzlocal was run on the EMS server, which resolved the situation.


I'd like to know if anyone else has encountered this error and how you resolved it.


Thank you all in advance.
#EMS

Best answer by Alan_

In my specific case, apache was not manually restarted:

[mpm_worker:notice] [pid 1093406:tid 1093406] AH00296: caught SIGWINCH, shutting down gracefully
[remoteip:notice] [pid 2368744:tid 2368744] AH03492: RemoteIPProxyProtocol: enabled on 0.0.0.0:9443
[mpm_worker:notice] [pid 2368744:tid 2368744] AH00292: Apache/2.4.66 (Ubuntu) OpenSSL/3.1.8 mod_wsgi/4.9.4 Python/3.10 configured -- resuming normal operations
[core:notice] [pid 2368744:tid 2368744] AH00094: Command line: '/usr/sbin/apache2'


After that, tzlocal kicks in and issue showed up.

6 replies

AEK
SuperUser
SuperUser
March 12, 2026

Hi Mandalorian

The error message seems to indicate that EMS couldn't login to the DB.

Try check on the DB node if the DB is up and reachable on the port 5432, then use tcpdump to see if EMS is trying to connect to the right port 5432.

AEK
Mandalorian
Explorer III
March 19, 2026

Hi @AEK,

Thank you for your feedback, but we need to understand something else now.
We've determined that the cause of the 500 error was due to a misconfiguration of the timezone within the VM hosting EMS:

/etc/timezone -> UTC
/etc/localtime -> CET

This misconfiguration has remained unchanged for weeks since the VM was set up and EMS was configured.

Fortinet has also updated its documentation regarding this issue. See "To install EMS -> section 5" (link below).

https://docs.fortinet.com/document/forticlient/7.4.5/install-and-migration-guide/169245/installing-ems-with-standalone-remote-db-without-docker

Now we'd like to understand why, with a misconfiguration that was always present, the error occurred weeks later.

I add as event history the extracted error logs:

tzlocal.utils.ZoneInfoNotFoundError: 'Multiple conflicting time zone configurations found:
/etc/timezone: Etc/UTC
/etc/localtime is a symlink to: Europe/CET
Fix the configuration, or set the time zone in a TZ environment variable.'

*********************************************************************

FATAL: server login has been failing, try again later (server_login_retry)
(SQLSTATE 08P01)


Thank you all in advance.

#EMS


"This is the way"
Mandalorian
Explorer III
March 26, 2026

@AEK + @Alan_ 

I am also including Fortinet official reference document in this thread:

https://community.fortinet.com/t5/FortiClient/Troubleshooting-Tip-500-Internal-Server-Error-when-accessing/ta-p/433600

What is not explained and what leaves us puzzled is why this discrepancy between the two time zone files did not cause any service interruptions for several weeks, but only after a certain amount of time had passed (about three weeks or more)


Thank you all in advance.

#EMS


"This is the way"
Alan_
Staff
Staff
March 26, 2026

Hello,

The situation you’re describing is very similar to what I experienced.

EMS was installed from scratch, and this discrepancy was present. There was no service interruption for a week. Then the Apache logs showed a graceful restart, and tzlocal utils began its checks, which triggered the issue.


You may want to check your logs to see whether Apache was restarted. Try searching for “resuming normal operations”.


It’s still unclear why the tzlocal utils check was triggered only after the Apache restart, though.

Mandalorian
Explorer III
March 27, 2026

Hi @Alan_ ,

Thank you for your feedback.
The "emscli service restart --name apache2" command was definitely not issued before the outage.
At this point, the only possible causes are tzlocal or some other EMS process that triggered the timezone check, which then triggered the 500 server error.

The only certain thing is that these errors emerged in chronological order from the logs extracted from the EMS server:

tzlocal.utils.ZoneInfoNotFoundError: 'Multiple conflicting time zone configurations found:
/etc/timezone: Etc/UTC
/etc/localtime is a symlink to: Europe/CET
Fix the configuration, or set the time zone in a TZ environment variable.'

*********************************************************************

FATAL: server login has been failing, try again later (server_login_retry)
(SQLSTATE 08P01)

Thank you all in advance.

#EMS


"This is the way"
Alan_
Staff
Alan_Answer
Staff
March 30, 2026

In my specific case, apache was not manually restarted:

[mpm_worker:notice] [pid 1093406:tid 1093406] AH00296: caught SIGWINCH, shutting down gracefully
[remoteip:notice] [pid 2368744:tid 2368744] AH03492: RemoteIPProxyProtocol: enabled on 0.0.0.0:9443
[mpm_worker:notice] [pid 2368744:tid 2368744] AH00292: Apache/2.4.66 (Ubuntu) OpenSSL/3.1.8 mod_wsgi/4.9.4 Python/3.10 configured -- resuming normal operations
[core:notice] [pid 2368744:tid 2368744] AH00094: Command line: '/usr/sbin/apache2'


After that, tzlocal kicks in and issue showed up.

Thought Leadership Security Summit. Outpace New Threats with AI - enhanced defense. Tuesday, Septmeber 15, 8:30 AM - 2:30 PM PT. The Golf Club at Newcastle, WA.
Virtual event | September 2026. SASE summit. The age of autonomous trust. Register here!
