How Remote SLAs work.
Performance SLAs (Health-Check in CLI) are a pillar of Fortinet SD-WAN; they are used to monitor the status of SD-WAN members.
Here is the most recent official documentation regarding them: Performance SLA.
There are five performance SLA detection modes:
active: The probes are sent actively. passive: The traffic measures health without probes. prefer-passive: The probes are sent when there is no new traffic. remote: Link health is obtained from remote peers. agent-based: Traffic health is measured from the fabric connectors.
This article is regarding a Performance SLA configured with the probe mode 'remote' (with the info regarding the link health obtained from the remote peers via ICMP probe packets), usually called Remote SLAs. It is necessary, first, to know how to configure them, which is explained here:
Embedded SD-WAN SLA information in ICMP probes After that, it is necessary to know that: This feature is available from the FortiOS firmware release v7.2.1. It is typically configured on FortiGates acting like an SD-WAN Hub, to choose the best SD-WAN member to send traffic, without actively monitoring all the paths to reach all Spokes. This feature works only with dial-up IPsec tunnels. It is necessary to have at least 2 Spokes connected to the Hub. Spokes must have at least 2 tunnels with each Hub. They influenced the FortiGates' decision regarding the SD-WAN member to choose, updating related route priorities. How route priorities influence FortiGate decisions is explained here:
Technical Tip: Routing behavior depending on distance and priority for static routes, and Policy Based Routes. For the 'return traffic', a FortiGate, like an SD-WAN Hub, uses the reply direction of the related session (here is how to read the session’s information:
Troubleshooting Tip: FortiGate session table information.
Making an example: considering an application Server reachable via the Hub LAN, the Hub sends the Server responses to clients connected to a Branch LAN, using the reply direction of the session, allocated for the related client request, without SD-WAN/routing lookup. Until the FortiOS minor release v7.4 with all related patches, an SD-WAN Spoke with a Performance SLA configured can transmit, using ICMP probes packets, only values measured and the Hub compares those values with his local threshold; starting from FortiOS v7.6.0, a FortiGate can transmit the information if a member is in SLA or out of SLA, in this way also the route priorities of the Hub, are updated according to the local Spokes threshold, that can be the different between different Spokes, as explained here:
Embedded SD-WAN SLA status in ICMP probes In FortiOS v7.4.8 and below, remote SLA on the Hub does not change status from pass to fail when the Hub does not receive ICMP probes anymore from a tunnel IPsec that goes down. Hub still applies the priority-in-sla to the routes that are received from the failed tunnel IPsec instead of priority-out-sla, causing temporary routing issues. Once the VPN tunnel is considered dead and flushed away, the related routes and remote SLA entry are removed. Starting with FortiOS release v7.6.0, the command remote-probe-timeout was introduced to address the issue explained in point 10. Hub will consider a probe lost after a while (20 - 3600*1000 msec, default = 5000) and will change the status of the related entry from pass to pktloss, applying the priority-out-sla correctly (the bug does not affect FortiOS v7.4.x).
config health-check
    edit <health-check name>
       set remote-probe-timeout <integer>
   next
Remote SLA Troubleshooting Guide.
Suppose a remote SLA was configured on an SD-WAN Hub, like this:
config health-check
    edit "REMOTE_SLA_T1"
        set detect-mode remote
        set sla-id-redistribute 1
        set members 3
            config sla
                edit 1
                    set link-cost-factor latency
                    set latency-threshold 100
                    set priority-in-sla 10
                    set priority-out-sla 20
                next
The expectation is that all routes coming through the SD-WAN member 3 should have a priority of 10 or 20. The condition to be satisfied is that: The member is UP and monitored. The routes coming through the member are associated with it. The member is periodically measured, and measures are received from the Hub. The Hub reads the measures received. The Hub updates the priorities of associated routes.
The first, second, and fifth activities are performed by the daemon of the Hub called lnkmtd, the third from the Spokes, and the fourth from another Hub's daemon called lnkmt_passive. In a Fortinet SD-WAN Hub and Spoke deployment with BGP on loopback as explained here: BGP on Loopback and with additional paths feature configured; for each subnet advertised from each Spoke, the Hub should have a route associated with each SD-WAN member usable to forward the traffic. To verify the third and fourth conditions, it is possible to use this command:
diagnose sys sdwan health-check remote REMOTE_SLA_T1

Remote Health Check: REMOTE_SLA_T1(3)

  Passive remote statistics of Hub_T1(20):

Hub_T1_0(10.0.0.3): timestamp=01-17 17:42:52, latency=0.515, jitter=0.084, pktloss=0.000%, SLA id=1, pass
To verify the second is necessary to analyze the routing table, to see if the command is:
get router info routing-table all
Supposing that in the routing table there is a route for a subnet announced from a Spoke through the tunnel Hub_T1_0, configured like SD-WAN member 3, so monitored from the Remote SLA called REMOTE_SLA_T1 shown at the beginning of the article, has the default priority 1, as shown here:
B 10.200.2.0/24 [200/0] via 10.150.1.2 (recursive via Hub_T1 tunnel 10.0.0.1 [1]), 00:21:53
There is incorrect behavior of the Hub because it should have priority 10 if the performances measured are below the threshold, otherwise it should have priority 20. For the first it is necessary to understand with which Spoke the tunnel is created, making the hypothesis of a dialup IPSec tunnel configured on the Hub, to find the name of the tunnel created with a specific Spoke way could go to from the Hub GUI to: Dashboard -> IPSec Monitor page and filtering, for example, the Remote Gateway Column, specifying the IP of the interface used from that IPSec tunnel on the Spoke, as shown here: 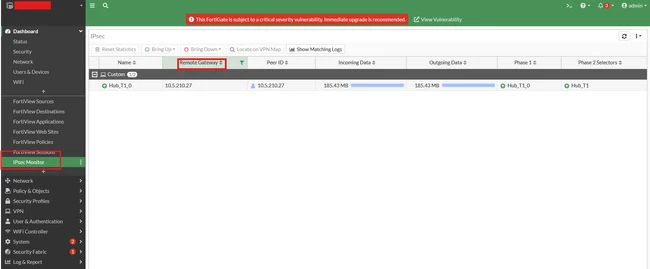 Here is an explanation of how to add the IPSec Monitor page in the GUI:
Adding FortiView widgets Returning to the wrong behavior observed, it could be caused by bug 1109286, fixed starting from the FortiOS release v7.6.3 and affecting all FortiOS v7.2, v7.4 patches, and the first 2 patches of the minor release v7.6:
Technical Tip: FortiOS firmware version terminology.
The trigger condition of the bug is a crash of the Hub daemon iked which causes a rekey of all IPsec tunnels.
To see all daemon crashes, execute the following from the CLI:
diagnose debug crashlog read
If there was an IKED crash, similar rows will be listed:
755: 2024-12-03 20:25:04 <00565> firmware FortiGate-3400E v7.2.5,build1517b1517,230606 (GA.F) (Release)
756: 2024-12-03 20:25:04 <00565> application iked
757: 2024-12-03 20:25:04 <00565> *** signal 11 (Segmentation fault) received ***
758: 2024-12-03 20:25:04 <00565> Register dump:
The are multiple causes for an iked crash and need to be investigated with a ticket to the Fortinet TAC; one of them is: in an SD-WAN Hub done with a FortiGates Cluster and with more than 3000 Spokes a crash with signal 11 can be caused by the bug 0951667, resolved in the FortiOS firmware release v7.2.11 and v7.4.2 and all newer. After the crash and until the entire Cluster (not only a unit) is rebooted, the priorities will no longer be updated for many routes. A workaround to solve the issue is to kill the process created by the lnkmtd daemon. Here is how to kill a process:
Technical Tip: Find and restart/kill a process on a FortiGate by the process ID (PID) via pidof
The same method can also be used in case the remote health-check does not update upon the removal of health-check on remote end. Useful info:
As of FortiOS v7.6.3, the default values for probes-timeout are changed for 'remote' and 'agent-based' detection modes: the new values are 60000 milliseconds for the remote mode and 5000 milliseconds for the the agent-based mode. If a FortiGate reboots with a non-default value of the the probe-timeout of a Performance SLA in remote probe mode, the configured value will be lost. It will be necessary to configure the value again manually, but a value that is too strict may cause routing issues. It is recommended to use the default values indicated before. This incorrect behavior is fixed in FortiOS 7.6.1 (bug ID 1078608), as indicated in the Resolved issues. After a probe-timeout value change, the FortiGate will move all Remote SLAs to DEAD status for all SD-WAN members monitored, and will await new probe packets to understand the new status to assign to the member. This causes nsm and zebos daemons to peak with possible related issues, such as SNMP traps not being managed. If it is necessary to change the probe-timeout value in an environment in production, the activity should be performed in a maintenance window. The following article explains how to detect daemon peaks:
Technical Tip: Using the 'diagnose sys top' CLI command The daemon peaks problem should disappear within a few minutes after the configuration change. Related documents: Documents and articles regarding Fortinet SD-WAN Troubleshooting: Article regarding IPsec Troubleshooting on FortiGate: | 



